coreAI can now run language models and embeddings on European infrastructure through a deal with OpenRouter. This means the AI request itself – the question and the content it answers from – is processed by providers within the EU/EEA, not on servers in the US. For anyone with Norwegian or European privacy requirements, this removes one of the hardest trade-offs in adopting AI.
#What does European infrastructure mean in practice?
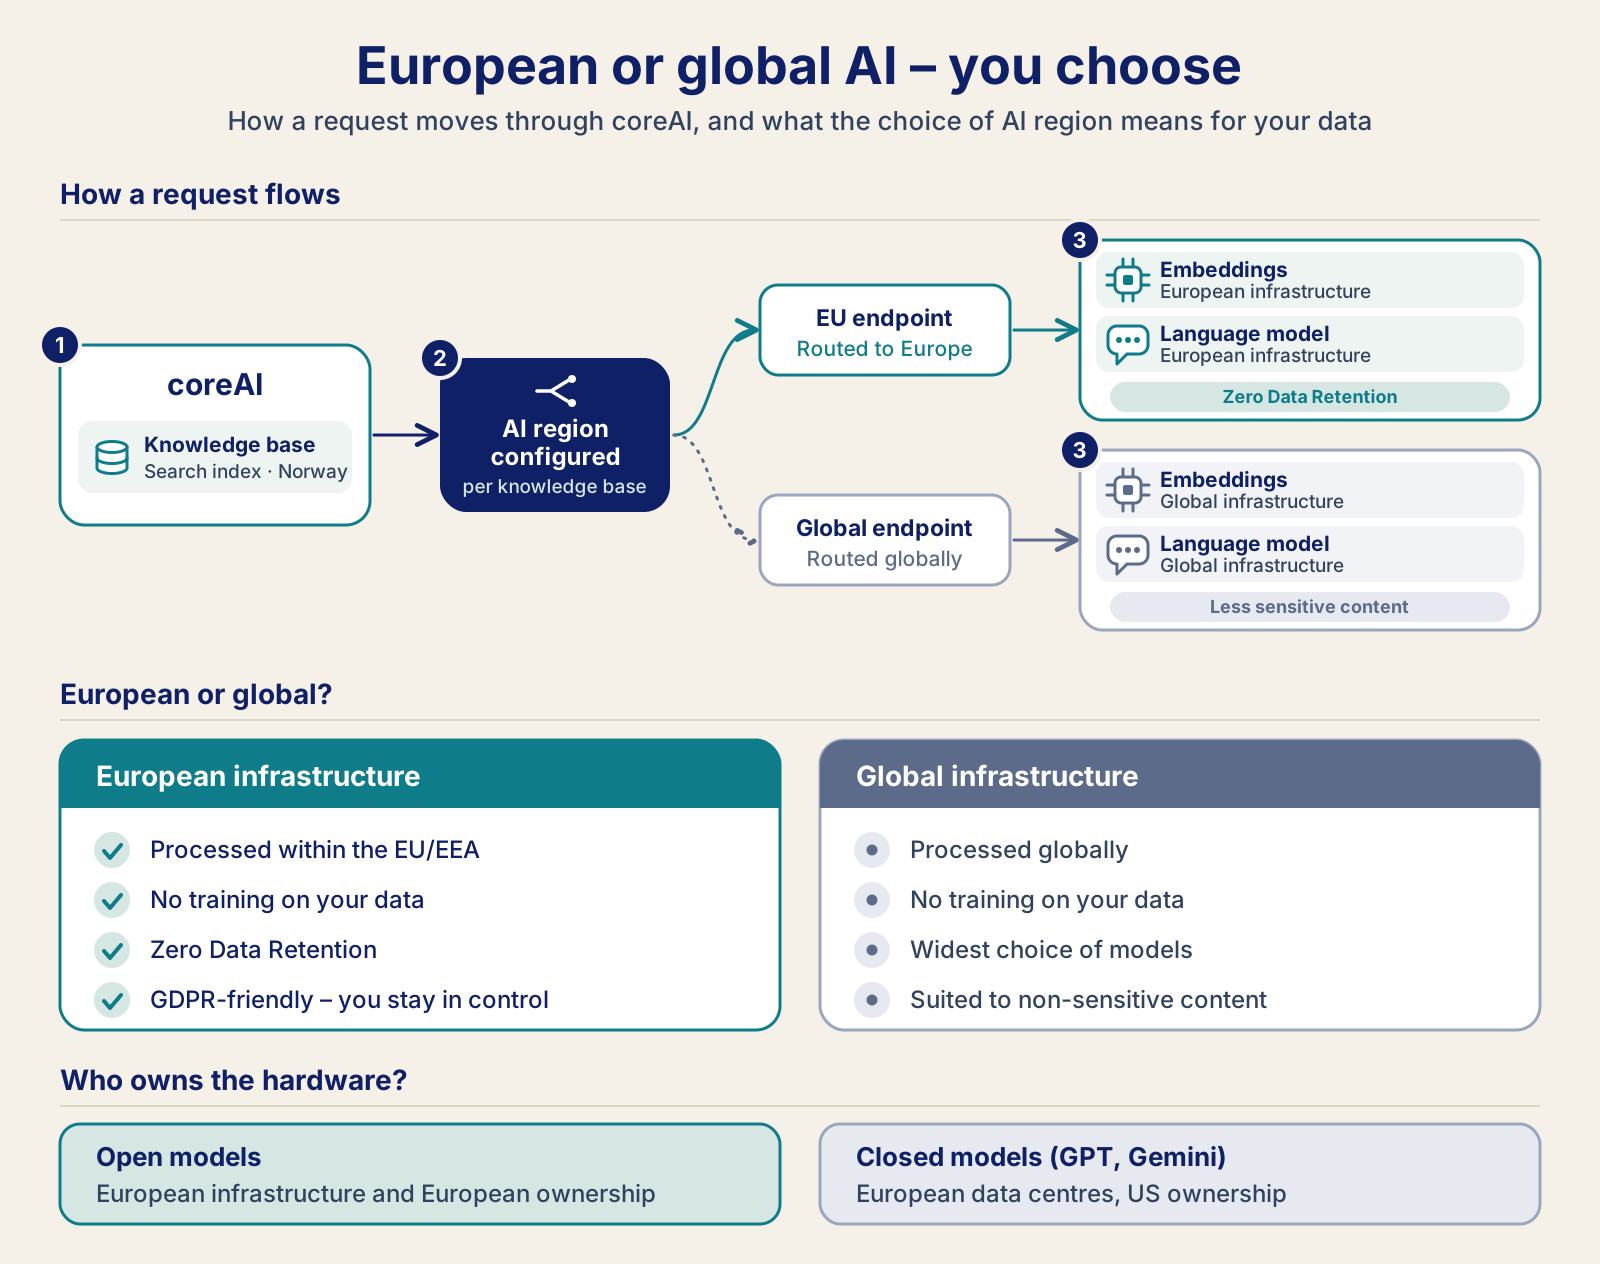
European infrastructure means the language model and the embeddings model run on data centres located in the EU/EEA, and that requests are routed there through OpenRouter's European endpoint. coreAI then sends the call to eu.openrouter.ai instead of the global endpoint, and OpenRouter forwards it only to providers that offer the model on European infrastructure.
In practice we distinguish between three layers, and all three matter for privacy. The knowledge base always sits on Norwegian infrastructure, while the embeddings model and the language model follow the AI region you choose:
- your knowledge base and search index, which always sit on Norwegian infrastructure
- the embeddings model that vectorises the content, which follows the AI region
- the language model that formulates the answer itself, which follows the AI region
It's the last two layers – the embeddings model and the language model – that previously most often sat outside Europe. With the European AI region the entire chain stays within the EU/EEA for the models available there.
#A simple choice per knowledge base
You choose the AI region per knowledge base – that is, which infrastructure the embeddings model and the language model run on, where available. The choice is a simple setting on the knowledge base – not a development project – so you can run one knowledge base on European infrastructure and another on global, depending on how sensitive the content is.
Not every model is available on European infrastructure yet. For the models that are, the European AI region appears as an available option; for those that aren't, you fall back to the global option. So you always see what is actually possible for the model you've chosen, and can choose deliberately.
#GDPR, data storage and no training
Whichever AI region you choose, your content is never used to train the models. With the European AI region, requests also run under Zero Data Retention (ZDR): your content is not stored after the answer is delivered. The combination of data processing within the EU/EEA, no storage and no training is what makes the setup GDPR-friendly.
Concretely, ZDR means a request is processed in memory to generate the answer and then discarded. There is no log of the content itself at the model provider. Nothing you send in ends up in a training dataset – not even when you choose the global AI region. The data responsibility and control remain with you.
#Guaranteed European infrastructure – but not always European ownership
It is guaranteed that the embeddings and language models run in Europe on European infrastructure, but the company that owns the hardware may in some cases still be US-owned. The distinction is between where the computation happens – always within the EU/EEA – and who owns the data centre it happens in.
For the open models, execution can happen on European infrastructure without the owner being a US company; there you get both European data processing and European ownership. The closed models from the major providers, however, run on the providers' own data centres: the GPT models run on OpenAI's European data centres, for example, and the Gemini models on Google's. The computation then happens in Europe, but ownership of the hardware still lies with a US company.
OpenRouter, which routes the requests onward, is also a US-owned company. What we guarantee is that the European models are processed within the EU/EEA under ZDR and without training on your data – regardless of who owns the hardware behind it.
We consider this good enough for the vast majority of use cases: as long as requests are processed in the EU/EEA, not stored and not used for training, the practical privacy risks are small – even when the hardware is owned by a US company. If you also need European ownership of the hardware, you choose one of the open models that run with European providers.
#coreAI on your own hardware
For organisations with particularly strict data control requirements, there is a solution that goes a step further: you can run the coreAI platform itself on your own or a partner's hardware. This means that not just the AI requests, but the entire solution – including the knowledge base, search index and application logic – runs within your own operating environment, without anything leaving your infrastructure.
This is relevant if you:
- have requirements that no data leaves your own network or server room
- want full control over updates, availability and operational configuration
- operate in an industry with specific regulatory or security requirements for data processing
- want to offer coreAI as a service to your own customers through your partner operation
In such a setup, coreAI is installed on servers you control yourself – either internally in your organisation or with a Norwegian or European partner company. You choose which language model to connect, including open models that can run entirely locally without any traffic leaving your environment.
#How to get started
Choose the European AI region on the relevant knowledge base where the option is available, and requests are automatically routed through Europe. If you want to run the entire coreAI platform on your own hardware, get in touch to discuss setup and requirements. To see how the knowledge base fits with the rest of the solution, see the knowledge base solution.